Almost Timely News: 🗞️ What Are Open Weights Models? (2026-10-18)

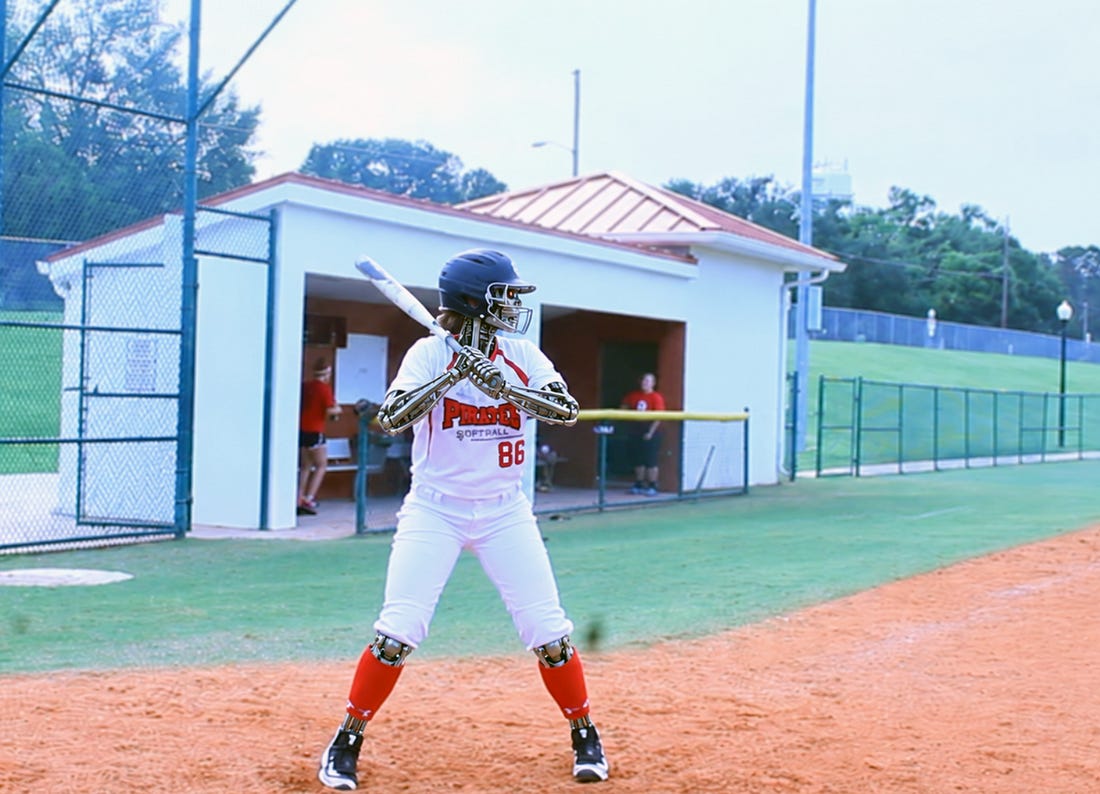
Almost Timely News: 🗞️ What Are Open Weights Models? (2026-10-18)Teaching a Terminator to play softball
Almost Timely News: 🗞️ What Are Open Weights Models? (2026-10-18) :: View in Browser
The Big Plug(s)🚗 Missed MAICON 2026? You can catch the replay of my session here! ✍️ Enroll in my new course, AI for Writers and learn how to make AI write better. My Unofficial LinkedIn Algorithm Guide is updated for October 2026! 👉 Get the paid version here, USD 20, with one-pagers and AI Skills. Content Authenticity Statement95% of this week’s newsletter was made by me, the human. The lead image is generated by ChatGPT’s Image model. Learn why this kind of disclosure is a good idea and might be required for anyone doing business in any capacity with the EU in the near future. Watch This Newsletter On YouTube 📺
Click here for the video 📺 version of this newsletter on YouTube » Click here for an MP3 audio 🎧 only version » What’s On My Mind: What Are Open Weights Models?This week, a reader request from Claire who asked over dinner at MAICON if I could explain open weights models more, because it’s a term heard a lot, but people don’t understand what they are or why they’re important. Part 1: WeightsBefore we dig into open and closed, what are model weights? You’ve likely heard terms like models that have a certain number of parameters, like a 70 billion parameter model or a 9 billion parameter model or a trillion parameter model. To make this concrete, let’s express this in terms of softball. Bear in mind, my expertise is in AI, not sports, so if I get some of the sports terminology wrong, I apologize. Think of a softball player like a model architecture. You have some players who are batters, some who are outfielders, some who are pitchers. While you can move some players from position to position, in general, the more specialized the position, the less you can swap players. A pitcher and a catcher are hard to interchange. Let’s take this a step further into the absurd. Imagine you just got a shiny new T-800 Terminator robot, completely untrained. Instead of giving it a pulse rifle and hunting down humanity, you give it a baseball bat and you want to teach it to become the best softball player in the world. How would you do that?
You’d have to teach it things like grip position, swing, stride, stance, all the things a real softball player would learn to do through muscle memory. Those are parameters - all the things you can adjust in the robot’s memory to remember how to play softball. And there are different models of Terminators. Some are smaller and have fewer articulations - elbows that only bend a certain way, or limits to their running speed. They have fewer things available to tweak, fewer muscle memories to build, so they have fewer parameters. That means they’re ready to hit the field sooner - they need less training - but it also means they will screw up more because they simply can’t adapt to some situations. A deluxe T-800 has thousands, maybe millions of different things you can tweak. Where their lead elbow points, how far their hips are turned, when to swing, how to hold their hands to maximize a line drive. Even something like where their pinky finger is positioned on the bat can make a different in some situations. It takes a lot longer to teach this Terminator how to play softball because there are so, so many different things to learn. In this ridiculous scenario, the training data is literally softball training. You put the Terminator in a batting cage with a pitching machine and you throw millions of pitches at it, adjusting it incrementally. For an entire series of pitches, you increase the height of the left elbow by a millimeter at a time until you find the sweet spot for the left elbow. Once you find the sweet spot for something, the Terminator remembers it. That memory of exactly at what height their left elbow should be positioned to hit a line drive is a weight. The parameter is what, and the weight is how. Smaller models have fewer parameters, and thus fewer weights, fewer things to remember. When the field changes and the team takes the field, the smaller Terminator is ready faster because it has less to remember. The larger Terminator is ready slower because it has more to remember, but it’s more skilled at dealing with more situations. In AI, the fewer parameters, the less precise the model is. It’s faster, it’s less overhead, but it runs into trouble more frequently. When we’re talking about model weights, we’re talking about a database of all those tweaks for every parameter, exactly what makes it work best. That’s part of the reason why AI companies devour so much data. Model training is exactly like softball training. The ball is the data, by the way. Each pitch from the machine is a piece of data, and you’re trying to train the Terminator for every conceivable pitch. So now you can see why model training is so intensive and expensive - you have to test every parameter possible against every pitch possible. Do you hit a line drive better when your left elbow is 44 inches off the ground when the pitch is a curveball versus a straight pitch? To find that out, you need to test millions, billions, or maybe even trillions of pitches. You’ll hear terms like mixture of experts model sometimes. These models are faster because they have their knowledge segmented. Imagine the same Terminator, but instead of having to remember everything for every single situation, it can selectively just remember how to be a great outfielder when it’s in the outfield, and just remember how to be a great batter when it’s batting - and not have to remember how to bat when it’s in the outfield. Mixture of experts models select just the knowledge they need, rather than remember everything at once. That gives you the benefit of speed, but it sacrifices accuracy across domains. A Terminator who forgets how to run because it’s in the outfield and not on base might be less effective than a Terminator that remembers how to run AND how to catch - but that version would come at a higher memory cost. Finally, you’ll hear terms like model quantization. This is a technique where you sacrifice some accuracy for speed by rounding some of the weights. Instead of measuring every possible angle of a Terminator’s elbow or knee when it’s batting, you might round that down to angles like 15 degrees, 30 degrees, etc. And sacrifice some of those intermediate degrees because the performance boost they give is much smaller than the cost of storing the extra memories. Is there a huge difference in batting if the Terminator’s knee is bent at 23 degrees instead of 25 degrees? Probably not. In a softball-size nutshell, that’s what model weights are. They’re the specific settings that a model remembers on how to accomplish tasks best. Part 2: Open and Closed WeightsAlmost all the Western frontier models - those with the greatest capabilities - are closed weights models. You’re not allowed to see the parameters or weights, you can only talk to the models through their interfaces. You can infer some things by watching them work, but the precise weights are hidden. In our softball analogy, this is a Terminator softball player that never discloses the exact bend of its elbow or the speed at which its shoulders rotate compared to its hips. We can roughly observe how it swings a bat or catches a ball, but we don’t have the precise calculations it uses. And that Terminator plays for one team only - it’s never out of control of its makers. Claude Opus will always have a Claude jersey on. An open weights model is a model where we can see the weights by downloading them. In our analogy of the Terminator softball player, we can download its memories and see exactly where its pinky is on the bat and how much pressure it’s exerting. More important, this is a player that can be traded to other teams. Open weights models can be downloaded and traded and used outside of their model makers. For example, the Alibaba Qwen model family is open weights. You can download Alibaba Qwen in its various flavors and run it on your local computer if you have enough power. Qwen 3.8 27B is a very capable model (about on par with Claude Opus 4.6 or 4.7, two generations old) that you can download and run on a well-appointed MacBook. If our organizations were Terminator softball teams, we could make a copy of Alibaba’s star player and have it play for us. You can’t do that with Claude or GPT-6.1 or Gemini 4 - those are never models we can download and run ourselves, out of the control of their makers. We can use them only through the interfaces provided by their makers. Imagine how weird it would be for your softball team to start batting and a player from another team sort of subs in. That’s what’s happening when we use a closed weights model. Somebody not on our team goes up to bat for us. This becomes very important when you want to know why a model is doing what it’s doing. In an open weights model, you can extract out the weights to understand why a model made the choices it made. In a closed weights model, you can’t ever see that, so you can’t ever understand exactly why it made specific choices. In some cases, what a closed weights model maker calls a “model” might even be an ecosystem of models and non-model technology glued together, like the meme of three raccoons in a trenchcoat. It’s rumored, as seen on Reddit, that OpenAI’s GPT-6 model is a looped model, where the model is smaller but loops its outputs back through itself multiple times to achieve higher quality without needing to get bigger in terms of parameters and weights. Why don’t providers of closed weights models allow us to see the weights? In short, it’d be trivially easy to copy the models. Imagine our Terminator softball player sharing its exact memories of how to hit a home run on any pitch. That information would be supremely valuable to competitors. So why do open weights model makers release the weights of their models? Many of them don’t have the same profit motives. Some, like Mistral, are part of an effort to create sovereign AI for a region (the EU) so that Silicon Valley doesn’t have an exclusive lock on the technology. Others, like many Chinese AI model makers, also want to prevent Western hegemony AND integrate AI into low cost operations around the world. In fact, as of October 2026, globally, 78% of all AI usage goes through Chinese open weights models, with the remaining 22% being models from other parts of the world, primarily Silicon Valley. Chinese model makers make their models freely available to create a massive adoption base. Part 3: Why We Care About Open Weights ModelsIf closed weights models like GPT-6.1, Opus 5.5, Gemini 4 Argon, etc. Are so amazing, why would we consider open weights technology at all? If we get great performance, why would we settle for less? Privacy. Open weights models run on our infrastructure or on providers like DeepInfra and similar with Zero Data Retention policies by default. When we use closed weights models, we have to send our data to a provider like Anthropic or OpenAI, and they have shown that our data is not private there. In our softball analogy, OpenAI might let us use their Terminator but it’s always recording and sending back our data to its home team. Security. Closed weights model providers have varying levels of security based on how much you’re willing to pay. While many, especially at the enterprise level, have what you’d deem commercially acceptable security, if you’re dealing with truly sensitive information, there’s never a true guarantee of safety. The surest form of data safety and security is when your data never leaves your network, and open weights models running on your hardware, inside your network, governed by your IT department and cybersecurity department ensure that your data is as safe as the rest of your infrastructure. Cost. This is the biggest reason many folks from individuals to enterprises care about open weights models. Open weights models are substantially cheaper in most cases compared to closed weights models. For the same levels of intelligence and capabilities, you pay much less. For example, GLM-5.3 Flash is roughly equivalent, via Artificial Analysis, to Claude Opus 5.5 on low or Claude Sonnet 5.5 on Medium, but price-wise is 53.3x cheaper than Opus on input and 80x cheaper on output. This gets really important once you start talking agents, because agents use FAR more tokens than chat-based AI. When you use an agent like Claude Code, Claude Cowork, Muse, Hermes, OpenClaw, etc. a single turn by the agent can consume 3 million tokens easily. Using it all day can run up costs in the hundreds of millions or even billions of tokens, and when there’s an option that’s 50-80X less expensive, those savings add up super quick. Continuity. What would happen to your business if, tomorrow, Anthropic or OpenAI closed its doors? What would happen to your productivity if Anthropic made its prices 100x what they are now, or your company dramatically restricted your usage as Accenture just did, telling employees they can only use $29 a month? Business continuity is all about keeping things going no matter what, so if you have AI models that you control and are under your jurisdiction and infrastructure, then you have fallbacks if the frontier models are unavailable. Even for day to day operations, the big tech providers frequently have status issues, and when those happen in the middle of the workday, having the ability to switch providers seamlessly is essential. For example, one of my favorite models is Qwen3.6 35B-A3B. It’s fast, smart, and runs entirely on my Mac. I can run it with no internet at all - as long as I have electricity, I can use it anywhere, like on a plane at 35,000 feet over the Atlantic. When Claude goes down, I can just switch right to Qwen and be back in business immediately. Even something as simple as the dreaded “You’re at 97% of your usage plan for the week” warnings go away when you’re using open weights models on your own infrastructure. The only limit is your computational power. You can use as much AI as you want when you’re running it on your own machines. Explainability. When you have access to the weights, you can inspect the output of a model to understand why it did what it did. Open weights models’ thinking is directly output by the server you run it on, so you can see exactly how they thought about a task. This not only helps improve prompting, but for use in highly-regulated industries, this allows for explainability and provides a log for auditors. Freedom. Every AI model is censored in some way. Some models will refuse requests about certain political perspectives or points of view. Most models will refuse requests that could be construed as harmful, even when there are legitimate edge cases. For example, I work with one client in a regulated industry that deals with hazardous materials. Some of their basic topics are things that closed weights models will refuse to discuss, even though the client’s uses are lawful. An open weights model that has been adjusted can work with their data. Another example is cybersecurity; when OpenAI attacked HuggingFace, HuggingFace tried to defend themselves with closed weights models but the providers all refused to help. They turned to GLM-5.2 to defend themselves because it was willing to assist them. Customization. Open weights models can undergo what’s called post-training, where you use similar methods to change the weights after the fact. Thinking back to our softball analogy, your Terminator softball player might have come out of the box being a really good pitcher, but a mediocre batter, and you have an enormous amount of batting data you can give it to become a better batter. You can’t customized closed weights models like this, but you can absolutely customize open weights models to be better at specific tasks, often with a tradeoff that they might get worse at other tasks. Sustainability. Because open weights models are traditionally smaller in size than closed weights models, they often run using fewer resources. For example, on my MacBook Pro, I can run Qwen3.8 easily, and my MacBook Pro uses a scant 160 watts of power even at full blast, and no fresh water. While hyperscaler data centers can serve models efficiently at scale, locally run models don’t hyperconcentrate usage, putting much less strain on power and water infrastructure. Contrast this with something like xAI’s Colossus data center which built 59 unlicensed gas turbines that are flooding predominantly Black communnities in Tennessee and Missouri with massive air pollution. Part 4: Wrapping UpIf you’re wondering how to get started with open weights models, I wrote about that in February of this year and for the most part, the advice in that issue still holds true, so rather than reinvent the wheel, I’ll link you back to that article. The models listed in it are out of date, but the general process is still correct. Now that you’ve got a better understanding of what open weights models are and why they’re important, your next step is to decide which open weights models to try out, based on the hardware you own or the budget you have to spend. But given all the great reasons to try out open weights models from sustainability to privacy to tuning capabilities, today is a great day to dip your toes into the open weights model universe and find out just how accessible and affordable local AI can be. How Was This Issue?Rate this week’s newsletter issue with a single click/tap. Your feedback over time helps me figure out what content to create for you. Got More Feedback?👉 Please take my 6-question Reader Survey to tell me what you want! Here’s The UnsubscribeIt took me a while to find a convenient way to link it up, but here’s how to get to the unsubscribe.
If you don’t see anything, here’s the text link to copy and paste: https://almosttimely.substack.com/action/disable_email Share With a Friend or ColleaguePlease share this newsletter with two other people. Send this URL to your friends/colleagues: https://www.christopherspenn.com/newsletter For enrolled subscribers on Substack, there are referral rewards if you refer 100, 200, or 300 other readers. Visit the Leaderboard here. ICYMI: In Case You Missed ItHere’s content from the last week in case things fell through the cracks:
My Merch ShopI’ve been adding so much stuff that I’ve decided to bundle it all in what I call a Merch Shop, because otherwise there’s literally too much to keep track of and I run out of space in my own newsletter. So welcome to the Merch Shop! Courses: Books: Skills for Claude and Agentic AI:
Subscriptions: On The TubesHere’s what debuted on my YouTube channel this week: Advertisement: New AI For Writers Course“It’s not X, it’s Y!” “XYZ is the load-bearing feature here.” “XYZ is the entire argument. Everything else is incidental.” Does AI writing grind your gears? When you use it at work and it spits out dreck despite your best efforts, does that frustrate you? It’s not your fault - and believe it or not, it’s not AI’s fault either. It’s that great writing is inherently low probability, and AI is a probability engine that trades in high probabilities. In the new Trust Insights AI for Writers Course, I teach you how to use tools, analysis, data, and code to force AI to write much more like you, giving it measurable requirements that it can obey to give you what you want - writing that doesn’t sound like the Terminator went on a bender with a thesaurus. The course is 22 lessons and includes tools, skills, plugins, and how to use them all to generate the kind of writing you’d want to read, and retails for USD 397. ✍️ Claim your seat here and start making AI write the way you expect. Get Back To Work!Folks who post jobs in the free Analytics for Marketers Slack community may have those jobs shared here, too. If you’re looking for work, check out these recent open positions, and check out the Slack group for the comprehensive list.
Disclosure: I source these links from LinkedIn every week on the following criteria: New in the past seven days, Easy Apply on, remote roles, USA geography. How to Stay in TouchLet’s make sure we’re connected in the places it suits you best. Here’s where you can find different content:
Listen to my theme song as a new single: Social Good: Ukraine 🇺🇦 Humanitarian FundThe war to free Ukraine continues. If you’d like to support humanitarian efforts in Ukraine, the Ukrainian government has set up a special portal, United24, to help make contributing easy. The effort to free Ukraine from Russia’s illegal invasion needs your ongoing support. 👉 Donate today to the Ukraine Humanitarian Relief Fund » Events I’ll Be AtHere are the public events where I’m speaking and attending. Say hi if you’re at an event also:
There are also private events that aren’t open to the public. If you’re an event organizer, let me help your event shine. Visit my speaking page for more details. Can’t be at an event? Stop by my private Slack group instead, Analytics for Marketers. Required DisclosuresEvents with links have purchased sponsorships in this newsletter and as a result, I receive direct financial compensation for promoting them. Advertisements in this newsletter have paid to be promoted, and as a result, I receive direct financial compensation for promoting them. My company, Trust Insights, maintains business partnerships with companies including, but not limited to, Amazon, Talkwalker, MarketingProfs, Agorapulse, The Marketing AI Institute, Spin Sucks, and others. While links shared from partners are not explicit endorsements, nor do they directly financially benefit Trust Insights, a commercial relationship exists for which Trust Insights may receive indirect financial benefit, and thus I may receive indirect financial benefit from them as well. Thank YouThanks for subscribing and reading this far. I appreciate it. As always, thank you for your support, your attention, and your kindness. Please share this newsletter with two other people. See you next week, Christopher S. Penn Invite your friends and earn rewards
If you enjoy Almost Timely Newsletter, share it with your friends and earn rewards when they subscribe.
|





Comments